Optical over Copper
Breaking through copper cable limits, achieving Tbps-class aggregate bandwidth
Array-parallel architecture breaks through the physical limits of electrical interconnects, replacing copper with light to power next-generation AI compute infrastructure.
Shifting from single-channel rate limits to 2D channel count scaling, replacing copper with light to break physical interconnect bottlenecks
Breaking through copper cable limits, achieving Tbps-class aggregate bandwidth
1,000+ channel linear scaling, 1–10 Gbps per channel
16nm–130nm mature process, supply chain validated
32×32 – 100×100
Micron-Level Alignment
1,000–10,000 Cores
Si-Based PIN
Fundamental breakthroughs enabled by array-parallel architecture
| Metric | Array Photonics | Legacy Copper |
|---|---|---|
| Aggregate Bandwidth | 10–100 Tbps | <1 Tbps |
| Energy per Bit | <1 pJ/bit | ~10 pJ/bit |
| End-to-End Latency | <1 ns | Hundreds of ns (with DSP) |
| Bandwidth Density | 1 Tbps/mm² | Limited |
* Data based on lab prototype validation
End-to-end optical interconnect solutions from intra-node to cluster backbone
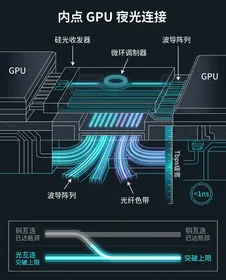
Replacing copper with Tbps-class bandwidth and sub-ns latency, breaking through electrical interconnect bandwidth ceilings
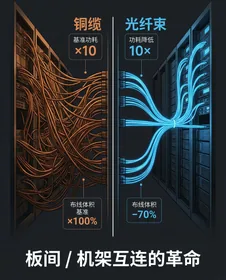
Fiber bundles replace copper cables — 10× lower power, 70% less cabling volume, dramatically simplifying data center thermal and cabling complexity
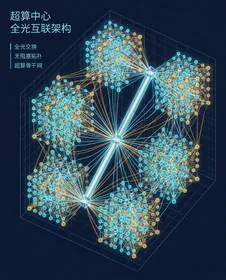
All-optical network architecture supporting efficient 10,000+ GPU cluster interconnection, eliminating electrical bottlenecks
Covering transmit, coupling, transmission, and receive — with clear performance targets for each module
Collaborating with leading OSAT partners to advance validation